Performance
Make compute go further.
Self-hosted processing designed for efficiency. Filter unwanted data before it reaches downstream systems, and run workers near your sources.
Choose your deployment →Fast, self-hosted telemetry pipelines.
Built visually. Managed with Git.
Free for individuals and for organizations with fewer than 250 employees. Source code on GitHub.
Filter, shape, and route logs and telemetry between your sources and destinations.
Kafka, Amazon S3, Syslog receiver, OTLP receiver, HEC receiver, and 15 more
debug: trace-101debug: trace-102debug: trace-103Splunk HEC, Elasticsearch, Amazon S3, Kafka, Apache Iceberg, and 8 more
Useful records.
Only the fields you need.
Search · Detection · Reporting
Build with real data
Capture a sample, edit your pipeline, and inspect the output. Save the input and expected result as a regression test.
Configure the step
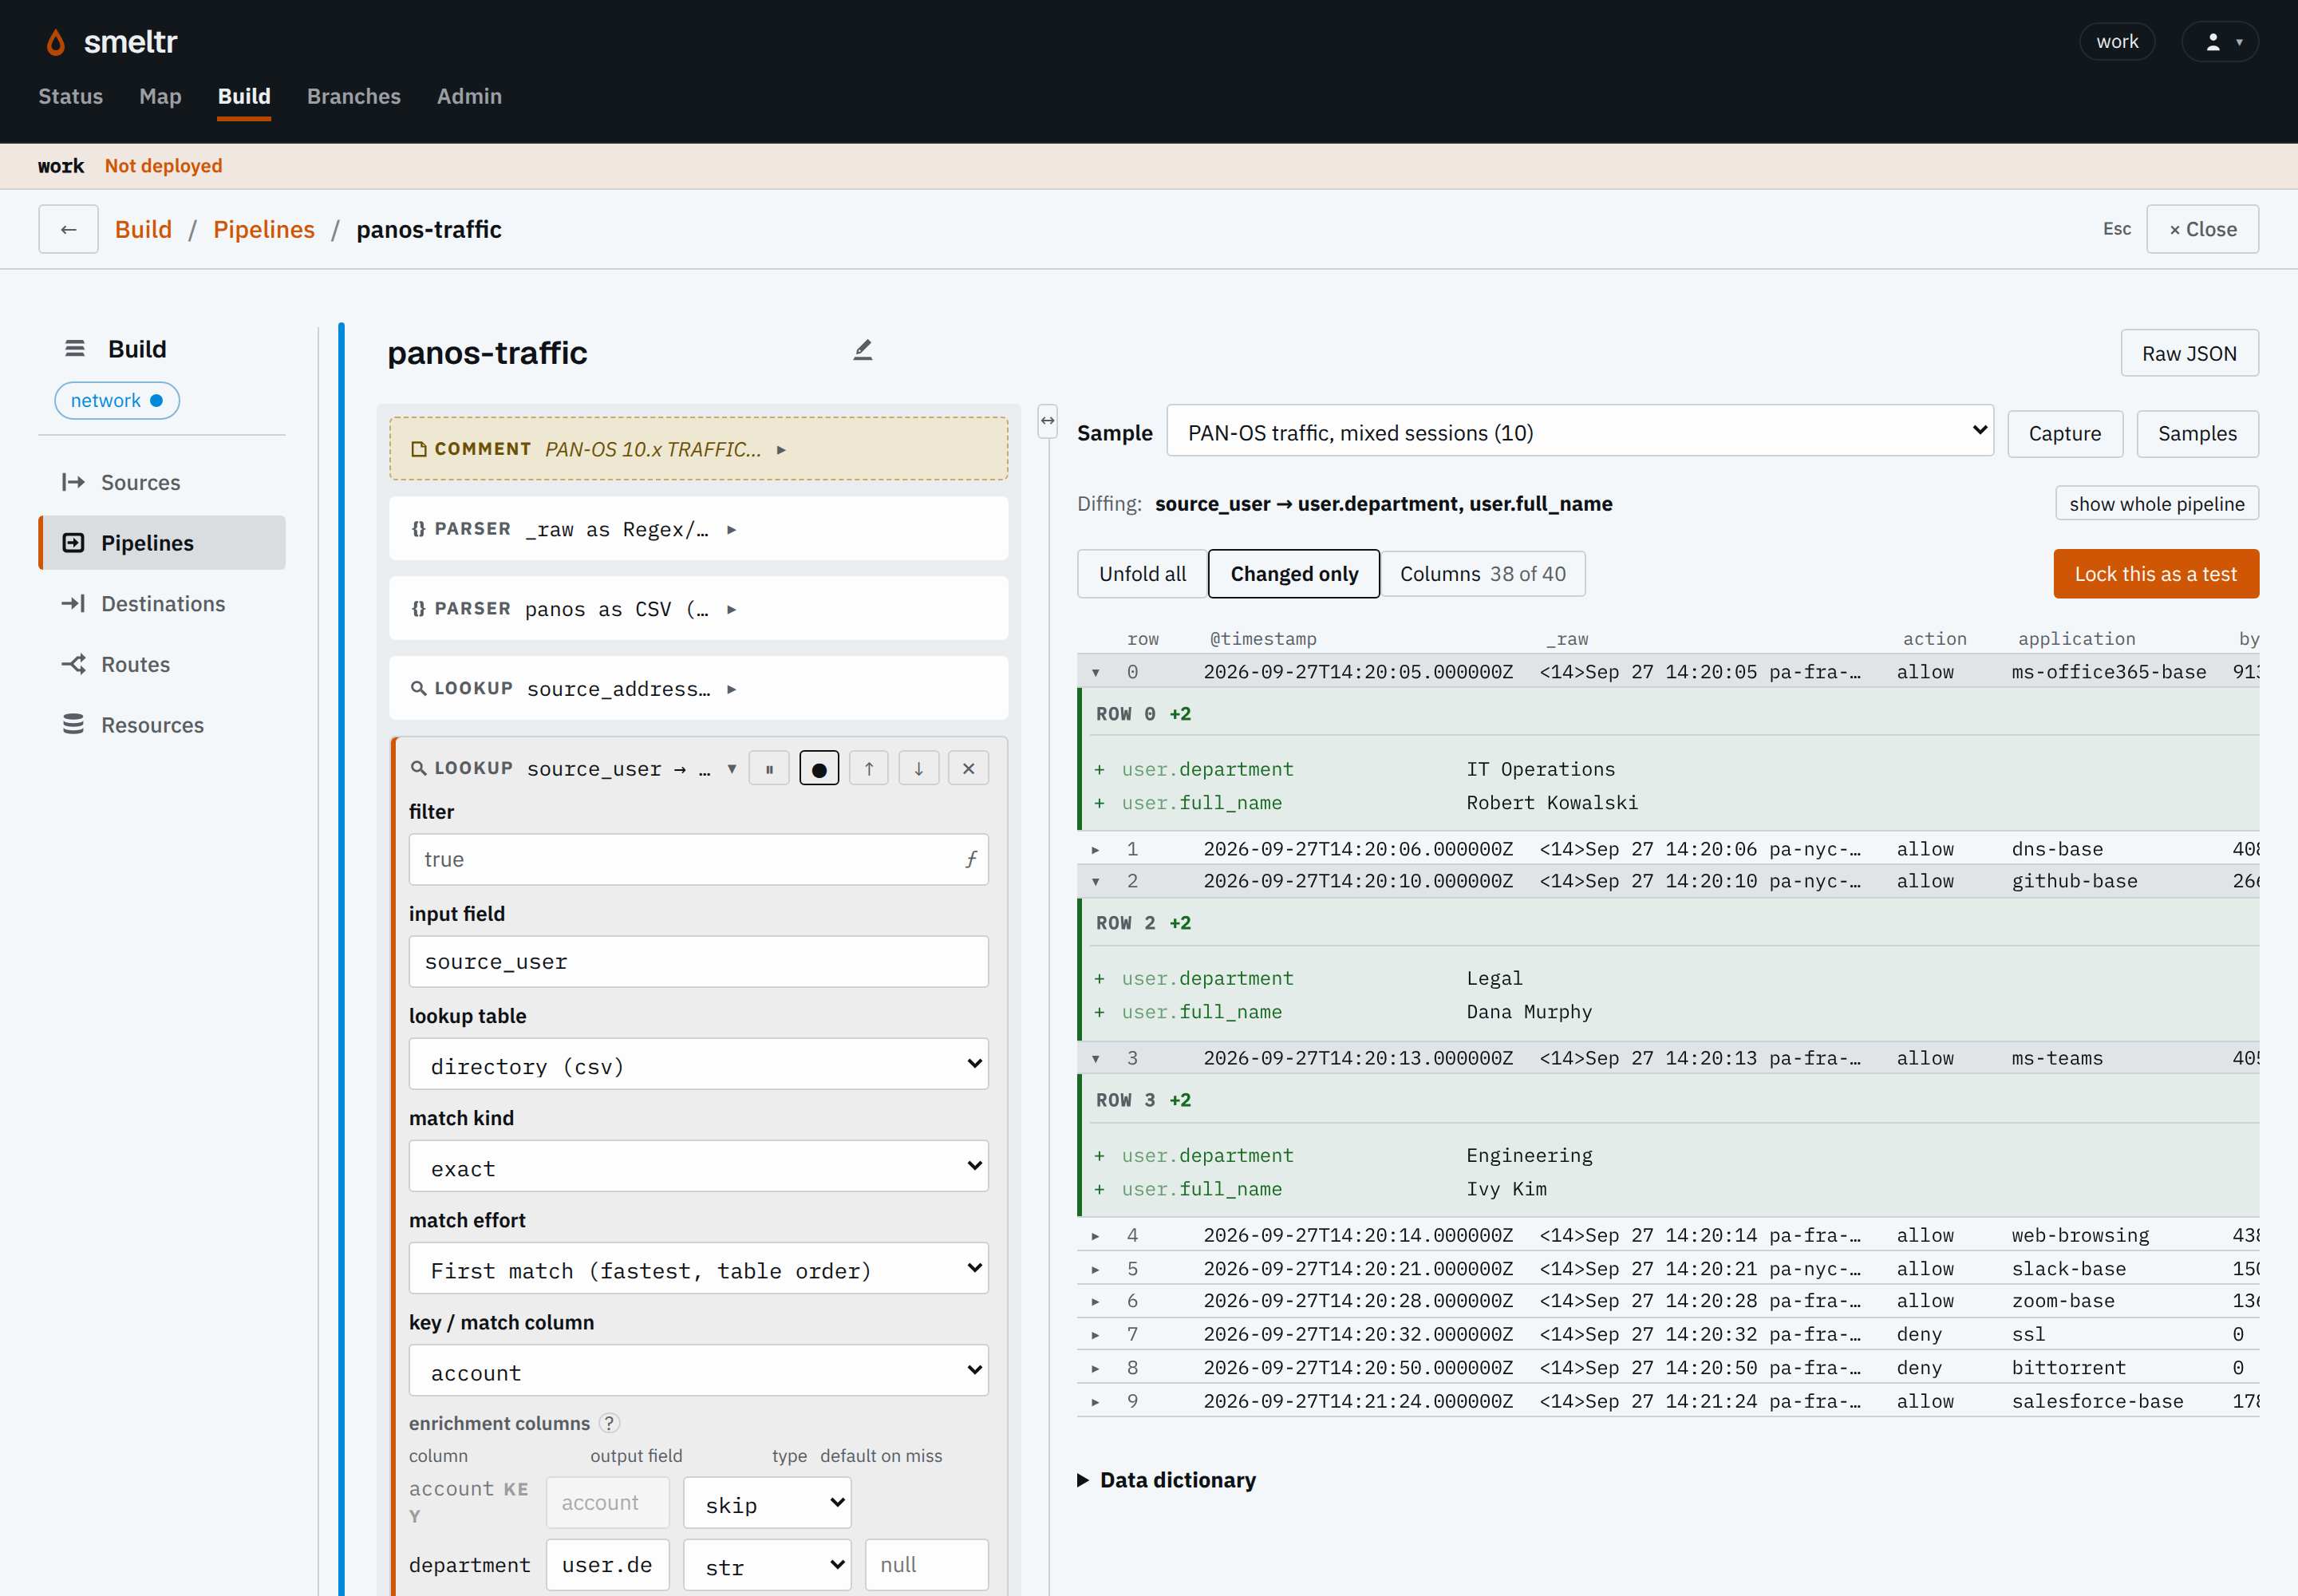
See what changes
Configure the step
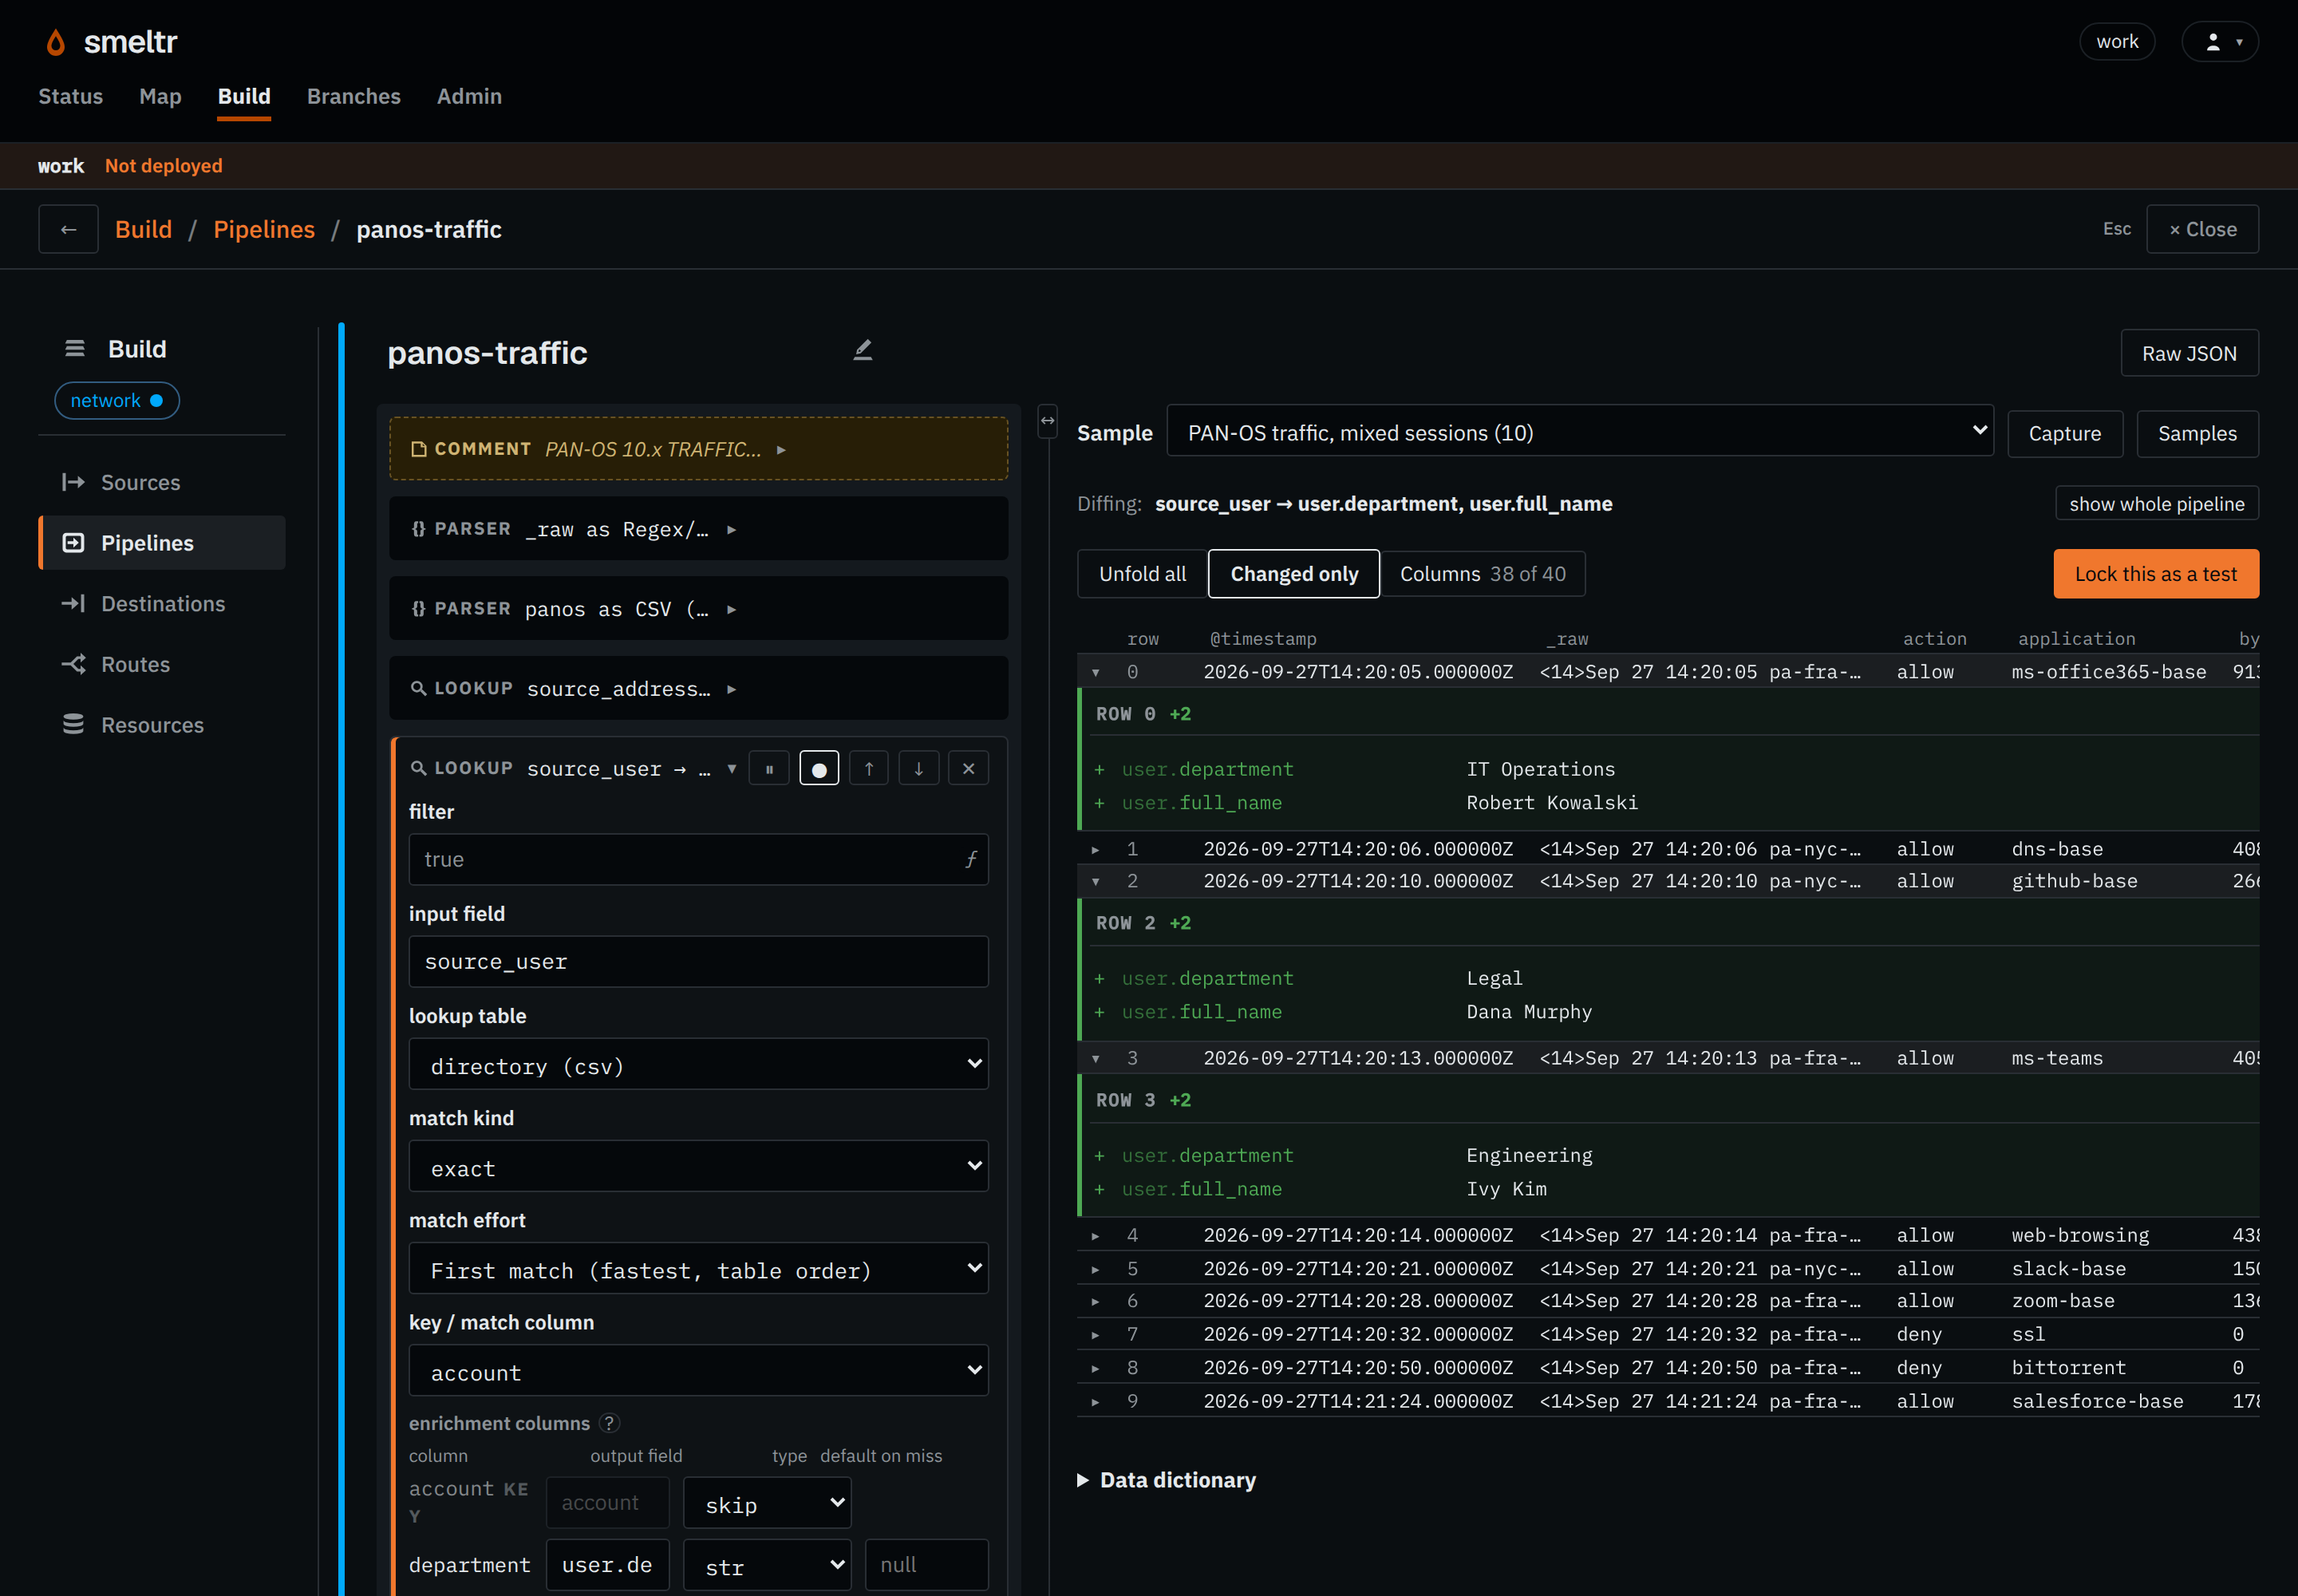
See what changes
Performance
Self-hosted processing designed for efficiency. Filter unwanted data before it reaches downstream systems, and run workers near your sources.
Choose your deployment →Change management
Develop on a branch. Commit your changes, review the diff and test results, then merge to main to deploy. Workers follow main.
Explore the Git workflow →Operations
Trace data flow, investigate warnings, and see which commit each worker runs. Verify the result at the destination.
Operate the fleet →